

LLM inference marketplace
Find inference that fits your budget.
Find a workable price for your next AI workload, or buyers for the inference capacity you already operate. CheapGPU connects the two sides through supplier offers.
Make the economics work on both sides.
Good ideas need workable inference costs. Available capacity needs a way to reach demand.
When the model fits, but the price does not
Look for an offer that makes your workload worth running, within a price you choose.
When comparing providers takes over
Bring model fit, supplier rates and offer terms into one search for a suitable match.
When capacity sits idle
Give the inference service you already operate another route to potential buyers.
When finding customers becomes another job
Put your offers in a marketplace where buyers are looking for inference.
For AI builders
Keep inference costs from limiting your ideas.
An application can work technically and still be too expensive to run. Start with the workload, then look for an offer that makes sense for it.
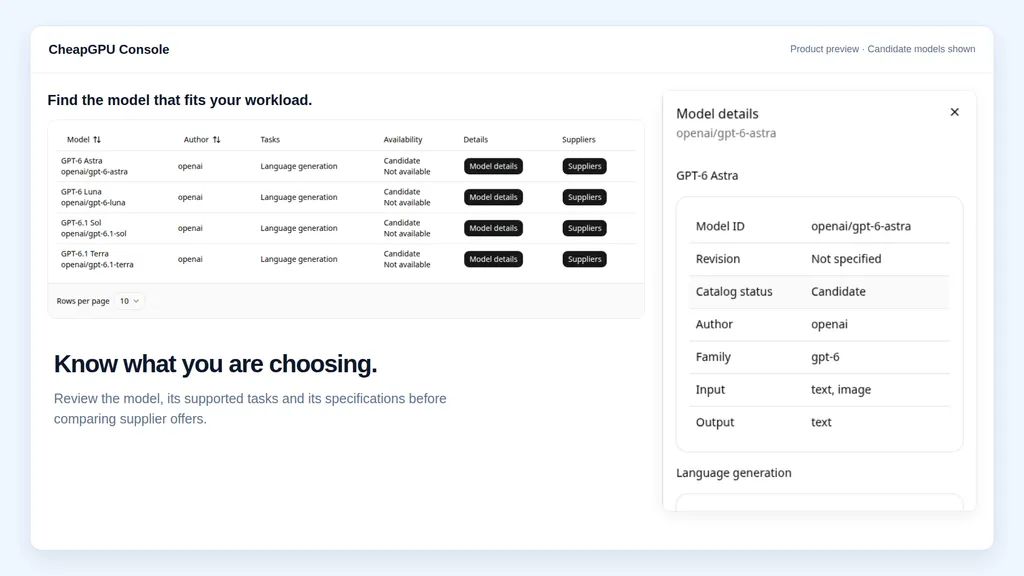
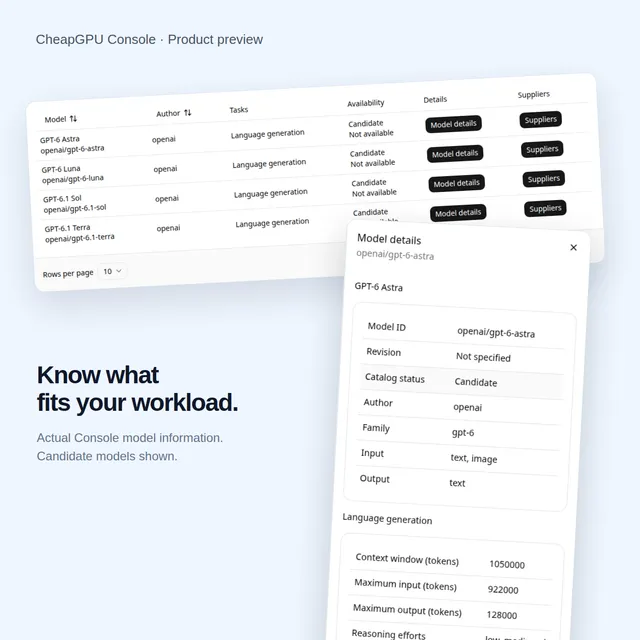
Know what the workload needs
Review model information and task support before you spend time comparing prices. The Console gives you a place to start that shortlist.
Compare the offers that matter
Each supplier sets its own rates. Look at the offer for your model and use case, so the price you compare belongs to the service you actually need.
Keep the price limit in your hands
The marketplace is designed to match eligible offers to the requirements and acceptable price you provide.
For inference providers
Find buyers for capacity you already run.
Running a model and finding customers are separate jobs. CheapGPU is designed to connect available inference capacity with buyer demand.
Reach beyond your existing customers
When your inference service has room for more work, a marketplace gives you another way to reach buyers for that capacity.
Keep operating the service you know
You run the models and the inference endpoint. CheapGPU is designed to bring buyer requests to eligible supplier offers.
Choose prices that work for your service
Set the rates for the inference you supply, based on the service you operate. You decide which prices make participation worthwhile; revenue depends on actual buyer transactions.
From your workload to a suitable supplier.
A marketplace designed around a practical match: the model you need, at a price you accept.
- 1
Define the job and the price limit
The buyer specifies the model, task and acceptable price for the request.
- 2
Match against eligible offers
CheapGPU is designed to select a qualified supplier offer that meets the request’s requirements.
- 3
Let the supplier run the model
The selected provider operates inference. CheapGPU handles routing and the platform’s accounting responsibilities.
Before you take the next step
What can I use today?
You can access the Console and read the integration drafts. Public inference APIs, supplier onboarding and production billing are not open yet.
Who sets the price of an offer?
Each supplier sets its own rates. The cost of a workload depends on the selected offer and its billable usage. Compare the applicable rates and terms for your needs.
How can I bring my inference service to CheapGPU?
Start with the supplier integration draft to understand the endpoint contract and compatibility requirements. Contact us to discuss the service you operate.
Does CheapGPU rent GPU servers?
CheapGPU focuses on buying and selling model inference. Suppliers operate the infrastructure; buyers look for an inference offer that suits their application.
Your next workload. Your available capacity.
Explore model information in the Console, or talk with us about bringing your inference service to the marketplace.